
An official website of the United States government
 United States Department of Labor
An official website of the United States government
United States Department of Labor

The .gov means it's official.
Federal government websites often end in .gov or .mil. Before sharing sensitive information,
make sure you're on a federal government site.

The site is secure.
The
https:// ensures that you are connecting to the official website and that any
information you provide is encrypted and transmitted securely.


This page provides documentation for Consumer Expenditure Surveys (CE) Public Use Microdata (PUMD), its conventions, files, sample code, and methodology.
Section 1. CE program
Section 2. CE PUMD
Section 3. Interview Survey
Section 4. Diary Survey
Section 5. Sample code
Section 6. Methodology
Section 7. Considerations
The Bureau of Labor Statistics (BLS) provides CE data on expenditures, income, and demographic characteristics of consumers in the United States. BLS provides these data in tables, CE databases, news releases, publications, and public use microdata files.
CE data are collected by the Census Bureau for BLS in two surveys, the Interview Survey for major and/or recurring items, and the Diary Survey for more minor or frequently purchased items. CE data are primarily used to revise the relative importance of goods and services in the market basket of the Consumer Price Index. CE is the only Federal household survey that provides information on the complete range of consumers' expenditures and income. For more information, see the overview section in the Consumer Expenditures and Income chapter in the BLS Handbook of Methods.
PUMD provide the individual responses to the two surveys from respondents. The data have been adjusted to protect the confidentiality of respondents. The PUMD allow researchers to analyze expenditure, income, and demographic data beyond what is provided in published estimates.
PUMD include data from both the Interview and Diary Surveys. Most files are analogous between the two surveys; however, the Interview Survey files contain roughly 50 additional detailed data files, as well as paradata files that provide detail about the collection process. All PUMD files cover a full calendar year. For years prior to 1996, file availability may be limited. Table 3 Interview Survey files and content lists the major files currently available, and their content. For a more comprehensive list of files provided in the PUMD, see the Dictionary for the Interview and Diary Surveys.
For both the Interview and Diary Surveys, the files use the following conventions:
The Interview Survey is a rotating panel survey in which approximately 11,000 addresses are contacted each calendar quarter that yield approximately 4,500 useable interviews. One-fourth of the addresses that are contacted each quarter are new to the survey. After a housing unit has been in the sample for four consecutive quarters, it is dropped from the survey, and a new address is selected to replace it. For more information, see the chapter Consumer Expenditures and Income in the BLS Handbook of Methods.
For the Interview Survey, the files use the following conventions:
Each annual data release of the PUMD is processed using new data and new disclosure avoidance guidelines. For quarters that appear in two different data releases, an "x" is added to the end of the file name. This "x" is used as an indicator to inform users that the two files were processed under a different set of rules and conditions and therefore the content may differ slightly. It is at the user's discretion as to which file to use.
From 2020 to 2023, PUMD packages for the Interview Survey only contain quarters 2, 3, and 4 of the year and quarter 1 of the following year. If you need quarter 1 of the year listed, please download the previous year's data package.
| Is the "x" included? | What file and release? | Did the files, methods, or data change? | Example |
|---|---|---|---|
|
No |
Fifth file of previous year's release | No, they stayed the same as in the previous four quarters in the package. | FMLIYYQ.sas7bdat |
|
Yes |
First file of current year's release | Yes, they changed from the previous year's version. | FMLIYYQx.sas7bdat |
| Flag value | Description |
|---|---|
|
A |
Valid blank; a blank field where a response is not anticipated |
|
B |
Invalid blank due to invalid nonresponse; nonresponse that is not consistent with other data reported by the CU |
|
C |
Blank due to "Don't know," refusal, or other nonresponse |
|
D |
Valid value; unadjusted |
|
E |
Valid value; allocated |
|
F |
Valid value; imputed or adjusted in some other way |
|
G |
Valid value; allocated and imputed |
|
H |
Valid blank for an expenditure that is a "parent record" where the expenditure was allocated to other records and the original expenditure was overwritten with a blank |
|
T |
Valid value; topcoded or suppressed |
|
U |
Valid value; allocated then topcoded or suppressed |
|
V |
Valid value; imputed or adjusted in some other way then topcoded or suppressed |
|
W |
Valid value; allocated and imputed or adjusted in some other way then topcoded or suppressed |
Table 3 summarizes the Interview Survey files currently available. If users encounter a file that is not listed below, consult the Dictionary for the Interview and Diary Surveys for additional details.
Table 3: Interview Survey files and content Name Content Variable periodicityⅰ Files per release Primary keysⅱ First year Last year FMLI
CU level Summary Expenditures Quarterlyⅲ 5 NEWID 1980 - CU level income, assets, and liabilities Annual CU characteristics and weights NA MTBI
Monthly expenditures Monthly 5 NEWID, SEQNO, ALCNO, UCC, RTYPE, EXPNAME, UCCSEQ, REF_MO, REF_YR 1980 - MEMI
Member level income Annual 5 NEWID, MEMBNO 1980 - Member characteristics NA ITBI
Detailed income Monthly 5 NEWID, UCC, REF_MO, REFYR 1980 - ITII
Imputed income iterations Monthly 5 NEWID, UCC, REF_MO, REFYR, IMPNUM 2004 - NTAXI
Estimated federal and state income taxes Annual 5 NEWID and TAXID 2013 Q2 2024 Detailed expenditure and non-expenditure data Quarterly, monthly, weekly, or NA Varies by year* NEWID, SEQNO, ALCNO 1980 - Data related to the survey process NA 1 NEWID 2009 - Data related to the contact history NA 1 NEWID, CNTCKEY 2009 - * For the specific detailed data files available, see PUMD dictionary.
The roughly 50 detailed data files include expenditure and non-expenditure information that is directly collected from sections of the Interview Survey (See the Survey materials page for more information). For years prior to 1994, there may be fewer files. The Dictionary for the Interview and Diary Surveys contains additional information related to the content and makeup for each of these files. Each detailed data file consist of five quarters of data. Because these files correspond to specific sections in the survey, they have a number of differences between them. These are the main differences:
Here is an example of the detailed data file VEQ (Vehicles, maintenance and repair) and some of the variables it contains.
Paradata files provide data about the interview process. Beginning in 2009, BLS began releasing paradata for the Interview Survey. BLS does not release paradata for the Diary Survey. Paradata are available in two datasets:
The Diary Survey is a separate survey in which approximately 7,500 addresses are contacted each calendar quarter that yield approximately 3,000 useable interviews.ⅳ After a housing unit has been in the sample for two consecutive weeks, it is dropped from the survey, and a new address is selected to replace it. For more information, see the chapter Consumer Expenditures and Income in the BLS Handbook of Methods.
For the Diary Survey, the files use the following conventions:
| Flag value | Description |
|---|---|
|
A |
Valid blank; a blank field where a response is not anticipated |
|
B |
Blank due to invalid nonresponse; nonresponse that is not consistent with other data reported by the CU |
|
C |
Blank due to "Don't know," refusal, or other nonresponse |
|
D |
Valid value; unadjusted |
|
E |
Valid value; allocated |
|
T |
Valid value; topcoded or suppressed |
For Diary Survey expenditures located on the EXPD files, the variable ALLOC can be utilized to determine if an expenditure has been adjusted, allocated, topcoded, or any combination of the three. Table 5 lists the allocation codes and its corresponding flag values.
| ALLOC Code | Description | Corresponding Flag |
|---|---|---|
|
0 |
Valid value, unadjusted | D |
|
1 |
Valid value, allocated | E |
|
2 |
Topcoded and allocated | T |
|
3 |
Topcoded, not allocated | T |
Table 6 summarizes the Diary Survey files currently available. Data prior to 1994 may include fewer files. If users encounter a file that is not listed below, consult the Dictionary for the Interview and Diary Surveys for additional details.
Table 6: Diary Survey files and content Name Content Variable periodicity Files per release Primary keysⅴ First year FMLD
Summary expenditures Weekly 4 NEWID 1980 CU level income, assets, and liabilities Annual CU characteristics and weights Annual MEMD
Member level income Annual 4 NEWID and MEMBNO 1980 Member characteristics NA EXPD
Detailed expenditure and non-expenditure data Weekly 4 NEWID and ALLOC 1980 DTBD
Detailed income Annual 4 NEWID and UCC 1980 DTID
Income imputation iterations Annual 4 NEWID, UCC, IMPNUM 2004
BLS provides sample code for PUMD. When using the code, users may want to consider these points:
Table 7 provides sample code for calendar year estimates:
| Purpose | Weights | Period | Estimates | Notes | Code |
|---|---|---|---|---|---|
|
Approximates CE table 1203 Income before taxes |
Weighted | Calendar | Aggregate annual expenditures; expenditure means and standard errors by income groups | PUMD estimates may not match the table estimates. For more information, see FAQ 26 on the CE FAQ page. | SAS |
|
Aggregates selected UCCs |
Weighted | Calendar | Aggregate annual expenditures; expenditure means and standard errors | The code integrates data from both surveys on a UCC level. For a list of UCCs, see introduction of hierarchical grouping files. | SAS R STATA |
This section describes the estimation procedures for the Interview Survey and the estimation procedures for the Diary Survey; the formulas to estimate weighted annual calendar year estimates; and sampling statements. BLS integrates information from both the Interview and Diary Surveys in its publications. Therefore any analysis limited to only the one survey may produce results that do not match the published CE estimates. In addition, users may find that estimates do not match the published estimates due to the non-disclosure criteria that are applied to the PUMD. For more information on non-disclosure requirements, see the Protection of Respondent Confidentiality page.
This section discusses procedures for estimating annual calendar year means with data from the Interview Survey. Field representatives interview CUs to collect the cost of all expenses during the prior three months. Data collected by each interview are treated as statistically independent - each quarter's interview is separately weighted to be representative of the population. For more information, see the collections and data sources section in the Consumer Expenditures and Income chapter in the BLS Handbook of Methods.
For the Interview Survey, users may want to consider the following general concepts:
When calculating data for 2016, interviews conducted in January 2017 cover expenditures made between October 2016 and December 2016, and are used to estimate data for these three months in 2016. Similarly, interviews conducted in March 2017 cover expenditures between December 2016 and February 2017 and are used to estimate data for December 2016. Thus, users have to use the first file for 2017 to estimate data for the last quarter of 2016. Charts 1 illustrates that concept. The green months show those that are in scope for the estimates of 2016 and the yellow months show those months in 2017 that out of scope.
Chart 1: Months in scope for quarter 5 (FMLI171)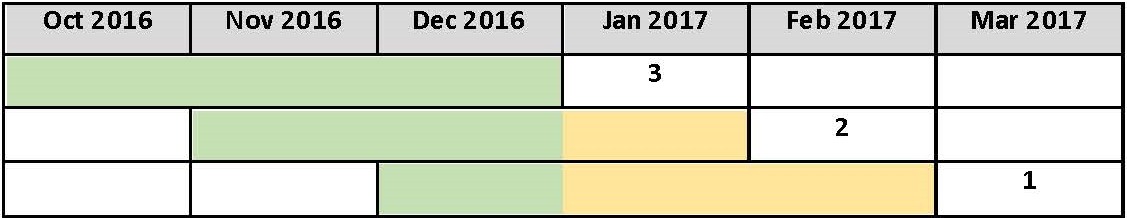
A similar differentiation of scope happens at the beginning of the year. The data collected in January of 2016 are not in scope for 2016 expenditures because the January interview collects data for the last 3 months of 2015. However, data collected in February and March 2016 are partially in scope. Data collected in February includes data for January of 2016, and data collected in March 2016 includes data for January and February 2016. See chart 2.
Chart 2: Months in scope for quarter 1 (FMLI161)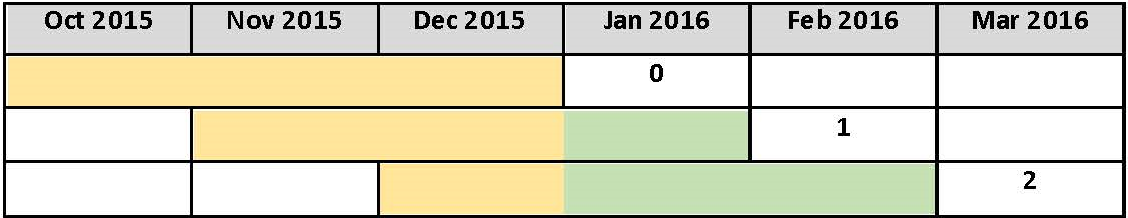
Finally, for the months April through December all months are in scope. For example, quarter 2 interviews conducted in April, May, and June collect expenditure data for January 2016 through May 2016, which are all in scope for 2016. See chart 3. The same holds true for Quarter 3 and 4.
Chart 3: Months in scope for quarter 2 (FMLI162)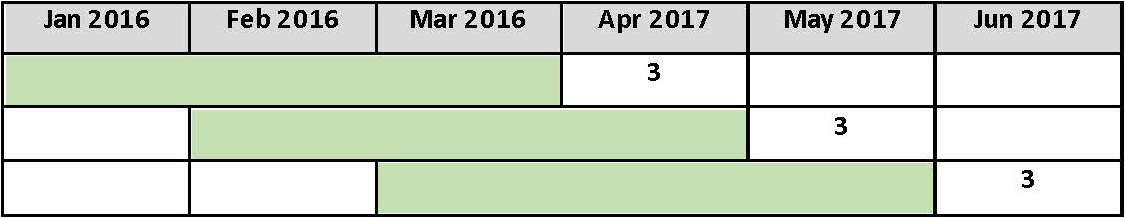
This section provides users of the Diary Survey with procedures to estimate annual calendar means.
CUs self-report a detailed description of all expenses using a diary for two consecutive 1-week periods. Data entries can start on any day of the week. Data collected each week are treated as statistically independent - each week's diary is separately weighted to be representative of the population. For more information, see the collections and data sources section in the chapter of Consumer Expenditures and Income in the BLS Handbook of Methods.
For the Diary Survey, users may want to consider the following concepts:
The formulas described below can be used to calculate weighted estimates that use data from both surveys. The formulas calculate annual calendar year aggregates, averages, and standard errors for expenditures and reported income. While these formulas can also be used to calculate annual averages of imputed income as well, they cannot be used to calculate standard errors. For more information on this topic, see the Description of Income Imputation Beginning with 2004 Data.
When integrating data across surveys, keep in mind that estimates created from the Diary Survey will yield a weekly amount and therefore, users will need to adjust their estimates so that each survey result represents the same period. Inflating the Diary Survey UCC estimate by a multiplier of 13, will result in a quarterly amount, which can then be summed with an Interview Survey estimate.
This section presents the methods to calculate the population, aggregate values, and average values for expenditures or income for a calendar year.
Denominator: PopulationNEWID = Identifier for one CU for one quarter
FINLWT21 = Weight of each NEWID
QNUM = Number of quarters in the analysis (Usually equal to 4 for a 1 year estimate)
MO_SCOPE = Indicator for the number of months in scope for each NEWID
For the first four quarters, MO_SCOPE is defined by the value of QINTRVMO:
For the fifth quarter, MO_SCOPE is defined by the value of QINTRVMO:
Numerator: Aggregate value
X = Expenditures or income variables. This formula can be used for quarterly, annual, weekly, or monthly data.
Quotient: Average value
Description of sampling and non-sampling errors
Sample surveys are subject to two types of errors, sampling and non-sampling. Sampling errors occur because observations are not taken from every unit in the entire population. Standard errors measure sampling errors. The primary purpose of standard errors is to provide users with a measure of the variability associated with the mean estimates. The sample estimate and its estimated standard error enable one to construct confidence intervals.
Non-sampling errors can be attributed to many sources, such as definitional difficulties, differences in the interpretation of questions, inability or unwillingness of the respondent to provide correct information, mistakes in recording or coding the data obtained, and other errors of collection, response, processing, coverage, and estimation of missing data. Estimates using a small number of observations are less reliable. Research articles examining CE measurement error and nonresponse bias are included in the CE library. BLS regularly examines CE data in the annual data quality assessment and compares CE results with other sources of federal statistics. For more information, see the Data Quality and Comparisons page.
For more information about standard errors including how to calculate them, see Standard Errors in the Consumer Expenditure Surveys.
The CE survey sample is a nationwide household survey representing the entire U.S. civilian noninstitutional population. It includes people living in houses, condominiums, apartments, and group quarters such as college dormitories. It excludes military personnel living overseas or on base, nursing home residents, and people in prisons. The civilian noninstitutional population represents more than 98 percent of the total U.S. population. For more information, see sample design in the chapter Consumer Expenditures and Income of the BLS Handbook of Methods.
Each CU included in the CE sample represents a given number of CUs in the U.S. population, which is considered to be the universe. Weighting is used to adjust the relative contribution of each CU to reflect the inverse of its selection probability, as well as to account for nonresponse and to match certain characteristics to known control totals. For more information, see sample design in the chapter Consumer Expenditures and Income of the BLS Handbook of Methods.
The state weights initiative was an effort to produce research microdata products that can allow users to explore consumer expenditure data at the state level. Research state weights are available for California, Florida, New York, and Texas from 2017 to 2023. Research state weights are available for New Jersey from 2017 to 2020. Beginning in 2021 BLS determined the sample in New Jersey could not support a state estimate (for more information, see the memo regarding this change). Research state weights are not available after 2023. For more information, see FAQ 16 on the CE FAQ webpage.
Care should be taken when analyzing public use microdata using the state weights, as the small number of households for some expenditures can cause the mean dollar estimate to be imprecise. The more aggregated summary variables will produce more precise estimates. Additionally, it should be noted that these weights are only for their respective states and cannot be used to make inferences about any other geographic areas. The provided data must be used in conjunction with the public use microdata to obtain state level estimates.
For users interested in using the 2017-2023 research state weights, please visit the CE PUMD files page.
The following are considerations users should be aware of when working with the PUMD. While PUMD contain a wealth of data, the CE surveys were designed with the specific purpose of finding out how U.S. consumers spend their money, and therefore may not be applicable to every research endeavor.
The CE surveys are designed to produce national expenditure estimates. The estimates are calculated from a relatively small sample of predominantly urban areas. Within these areas, CE samples a small percentage of those households.
At the subnational level, the current CE sample design allows data users to create estimates for 4 Census regions, 9 Census divisions, and over 25 metropolitan statistical areas. However, the PUMD do not contain information by county or zip code. For more information, see the CE geographic data page.
Data users cannot identify who bought an item or who consumed it because both CE surveys do not ask these questions. That limits the ability of data users to connect the data with demographic information of the specific purchaser or consumer.
However, data users may be able to infer some demographic characteristics for purchases by single member households because expenditures by single member household are likely purchased and consumed by that person.
Inferring demographic information for households with more than one member is more difficult than for single member households and would require strong assumptions.
Generally, the CE surveys only provide the total cost and no unit value. Thus an expense of $220 on wine could be one expensive bottle or a case of bottles.
However, the CE surveys do provide limited information on the quantity and quality of a few expenditures. For example, the Interview Survey indicates the number purchased for selected large items, like cars or appliances. The Diary Survey may identify the number of meals purchased away from home, but not how many people ate at each meal.
With respect to quality, the PUMD do contain roughly 50 detailed expenditure files that provide additional information about an expenditure. The information booklets distributed to respondents with the survey also describe what information data users can find in the data. For information on the questions the CE surveys ask, see the Survey Materials page.
Reported data on a Consumer Unit's (CU) income, income taxes, and financial assets may have limited analytical use because of two main factors:
The available detail for some categories may have limited analytical use due to the following major reasons:
Trend analysis of individual households is limited because respondents are interviewed for a fixed period. The specific duration depends on the survey, the type of data, and the respondent's willingness to participate.
Trend analyses of aggregated PUMD variables and to a lesser degree, items in CE tables, over several years are limited by the changes in collection and sampling methods. For example, every ten years BLS introduces a new sample design. Generally, when BLS introduces a new sample design, method, item, or question, the program does not create an overlap where both the old and the new version are available during the transition.
However, longitudinal analysis of major categories across several years is possible if the data user concludes that the changes in the underlying collection methods do not affect the overall trend. Generally, larger categories are less impacted than small categories. For a list of the main survey changes in the history of BLS, see Consumer Expenditures and Income: History in the BLS Handbook of Methods and the Improvements and protocol changes webpage.
ⅰ Variable periodicity refers to the period that a given value represents.
ⅱ Primary keys identify each unique record in the database.
ⅲ Quarterly summary expenditures are presented as two variables - one containing expenditures made in the previous calendar quarter and one containing expenditures made in the current calendar quarter.
ⅳ For more information on the number of contacted addresses and completed interviews, see the CE Data Quality Profile.
ⅴ Primary keys identify each unique record in the database.
Last modified date: October 29, 2026


